Schema Markup for AEO & GEO: The Complete JSON-LD Implementation Guide
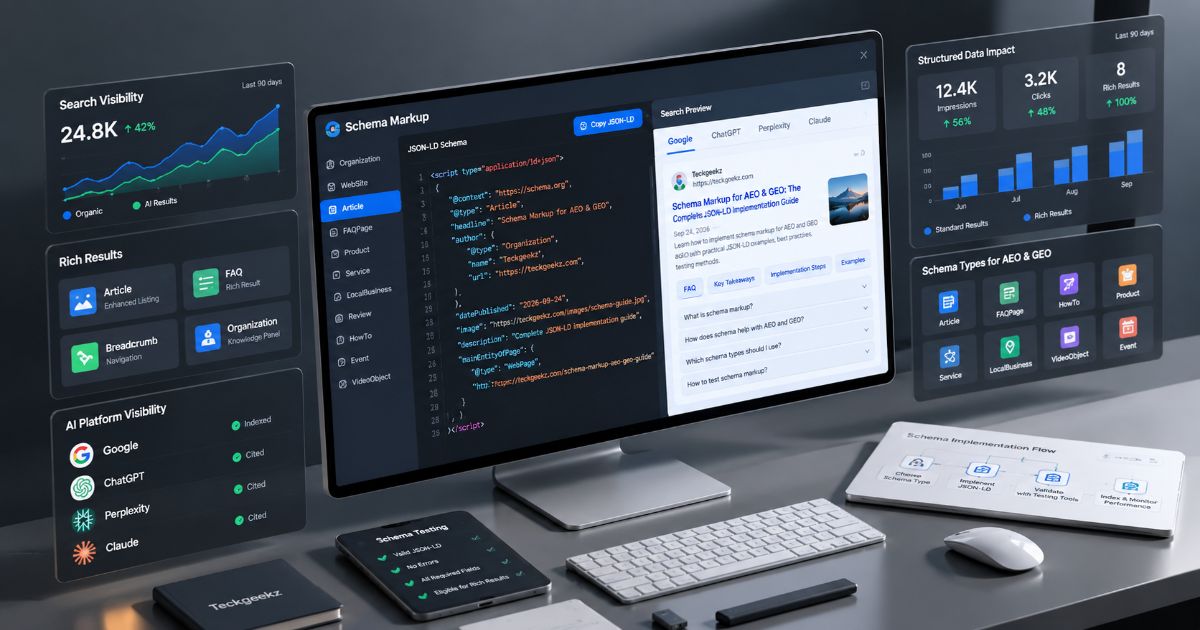
Quick answer: Schema markup is structured data, written in JSON-LD, that explicitly tells search engines and AI systems what your content actually is — not just what it says, but what kind of thing it represents (a question, an answer, a product, an organization) and how those things relate to each other. For AEO, the priority schemas are FAQPage, HowTo, and Speakable. For GEO, the priority shifts toward Organization, Person, and the @id-based linking that connects them into a single, unambiguous entity graph — because AI systems cite entities with confidence, and confidence depends on the entity being clearly and consistently identified, not just present.
This is the practical, code-level companion to the structural and content principles covered throughout this series — our guides on SEO vs AEO vs GEO, optimizing for Google AI Overviews, and getting cited by ChatGPT, Perplexity, and Claude all reference schema markup as a foundational requirement without covering the implementation in depth. This guide is that implementation.
What JSON-LD Actually Is, and Why It Matters More Than Most Businesses Realize
JSON-LD (JSON for Linked Data) is a way of embedding structured data directly into a page's HTML, using a standardized vocabulary — schema.org — that both search engines and AI systems have agreed to recognize and parse consistently. It sits in a <script type="application/ld+json"> tag, invisible to human visitors, read directly by machines.
The reason this matters more now than it did five years ago isn't that the technology changed — schema.org has existed since 2011. It's that the audience reading it has expanded. Traditional search engines have always used schema to power rich results — star ratings, FAQ dropdowns, recipe cards. AI systems now use the same structured data for a more fundamental purpose: reducing the ambiguity involved in understanding what a page actually is, what it's claiming, and — critically for GEO — what specific, identifiable entity is making that claim.
Without schema, a page is a wall of text a machine has to infer meaning from — good NLP models can do this reasonably well, but inference always carries uncertainty. With schema, the page explicitly declares: this is a question, this is its answer, this claim is made by this specific organization, which is the same organization described consistently across these other verified sources. That explicit declaration is what separates content a system can parse from content a system can cite with confidence.
FAQPage Schema: The Foundation of AEO Implementation
FAQPage schema is the most directly useful schema type for AEO, because it explicitly marks a question-and-answer pair as exactly that — removing any ambiguity about where a question ends and its answer begins, which is precisely the extraction problem a featured snippet or voice assistant answer needs solved.
{
  "@context": "https://schema.org",
  "@type": "FAQPage",
  "mainEntity": [
    {
      "@type": "Question",
      "name": "What is AEO?",
      "acceptedAnswer": {
        "@type": "Answer",
        "text": "AEO (Answer Engine Optimization) is the practice of structuring content so it can be extracted as a direct answer in featured snippets, People Also Ask boxes, and voice assistant responses."
      }
    }
  ]
}
A few implementation details that matter more than they might appear:
The question and answer text in the schema must match what's visibly present on the page. Google and other platforms have been explicit that schema misrepresenting visible content is treated as a violation, not a shortcut — the schema should describe what's genuinely there, not what you wish were there.
Answers should be self-contained, matching the AEO writing principles covered elsewhere in this series — a schema-marked answer that only makes sense with surrounding context defeats the purpose of marking it as an extractable unit in the first place.
Every FAQ block on a page should be represented as one mainEntity array, not multiple separate FAQPage schema instances — search engines have been explicit that a page should carry one FAQPage schema block covering all its genuine FAQ content, not fragmented duplicates.
HowTo Schema: Structuring Process Content
HowTo schema marks up step-by-step instructional content, giving search and AI systems an explicit structure for sequence, individual steps, and — where relevant — the tools or materials a process requires.
{
  "@context": "https://schema.org",
  "@type": "HowTo",
  "name": "How to Add FAQ Schema to a Web Page",
  "step": [
    {
      "@type": "HowToStep",
      "name": "Write the question and answer content",
      "text": "Draft a clear question and a self-contained, accurate answer that matches what's visible on the page."
    },
    {
      "@type": "HowToStep",
      "name": "Format as JSON-LD",
      "text": "Wrap the question and answer in FAQPage schema using the schema.org vocabulary."
    },
    {
      "@type": "HowToStep",
      "name": "Insert into the page head or body",
      "text": "Add the JSON-LD script tag to the page, then validate it before publishing."
    }
  ]
}
HowTo schema is genuinely useful for process-driven content — implementation guides, setup instructions, comparison-of-steps content — but it's worth applying selectively rather than by default. Content that isn't genuinely a linear, ordered process (a general explainer, an opinion piece, a comparison article) shouldn't be forced into HowTo formatting just because schema exists for it — mismatched schema, describing content as something it isn't, undermines the same trust and accuracy signal it's meant to build.
Speakable Schema: The Overlooked AEO Asset
Speakable schema explicitly marks which sections of a page are suitable for text-to-speech readout by voice assistants — a distinct concern from featured snippets, since a snippet-worthy paragraph and a voice-readout-worthy paragraph don't always have identical requirements (voice readout benefits from even tighter, more conversational phrasing than a visual snippet does).
{
  "@context": "https://schema.org",
  "@type": "WebPage",
  "speakable": {
    "@type": "SpeakableSpecification",
    "cssSelector": [".quick-answer", ".key-takeaway"]
  }
}
Rather than marking arbitrary paragraphs, Speakable schema references specific CSS selectors on the page — meaning the underlying page design needs a consistent, identifiable class or element (like a .quick-answer block) applied to the sections genuinely intended for voice readout. This is a schema type most businesses skip entirely, largely because it requires this small amount of coordinated front-end structure rather than being a pure content addition — which makes it a genuine differentiator for businesses that do implement it properly.
Article Schema: Establishing Authorship and Publication Context
Article schema (or its more specific variants — NewsArticle, BlogPosting) establishes the publication metadata that both search engines and AI systems use to evaluate currency, authorship credibility, and the broader context a piece of content sits within.
{
  "@context": "https://schema.org",
  "@type": "BlogPosting",
  "headline": "Schema Markup for AEO & GEO: The Complete JSON-LD Implementation Guide",
  "author": {
    "@type": "Person",
    "name": "Jeffrey Mathew",
    "url": "https://example.com/author/jeffrey-mathew"
  },
  "datePublished": "2026-04-01",
  "dateModified": "2026-04-20",
  "publisher": {
    "@type": "Organization",
    "name": "Example Travel Tech",
    "logo": {
      "@type": "ImageObject",
      "url": "https://example.com/logo.png"
    }
  }
}
The datePublished and dateModified fields deserve particular attention in an AEO/GEO context specifically, because — as covered in our guide to Google AI Overviews — currency is a real signal both AI Overviews and LLM retrieval systems weigh, and an accurate, honestly updated dateModified gives these systems explicit confirmation that content has genuinely been reviewed and kept current, rather than requiring them to infer freshness from weaker signals.
Organization and Person Schema: Where GEO Actually Begins
This is the schema category that matters most for GEO specifically, and it's the one most businesses under-invest in relative to FAQ and Article schema — because its value isn't immediately visible in a rich snippet the way FAQ schema's is. Its value shows up instead in the entity clarity and citation confidence covered throughout our guide to LLM citation optimization.
{
  "@context": "https://schema.org",
  "@type": "Organization",
  "@id": "https://example.com/#organization",
  "name": "Example Travel Tech",
  "url": "https://example.com",
  "logo": "https://example.com/logo.png",
  "sameAs": [
    "https://www.linkedin.com/company/example-travel-tech",
    "https://twitter.com/exampletraveltech",
    "https://www.crunchbase.com/organization/example-travel-tech"
  ],
  "founder": {
    "@type": "Person",
    "@id": "https://example.com/#founder"
  }
}
Person schema for individual authors or founders follows the same pattern, and — this is the detail worth genuinely understanding — should be explicitly linked back to the Organization via matching @id references, not just described independently on a separate page:
{
  "@context": "https://schema.org",
  "@type": "Person",
  "@id": "https://example.com/#founder",
  "name": "Jane Smith",
  "jobTitle": "Founder & CEO",
  "worksFor": {
    "@id": "https://example.com/#organization"
  },
  "sameAs": [
    "https://www.linkedin.com/in/janesmith-example"
  ]
}
Why Association Matters More Than Any Individual Schema Block
This is the concept most schema guides skip entirely, and it's arguably the single most important idea in this whole post for GEO specifically.
A schema block that exists in isolation identifies a thing. A schema block that's explicitly linked to other schema blocks — via matching @id values — identifies a thing's relationship to other things. An AI system doesn't just want to know "this page mentions an organization called Example Travel Tech." It wants to know: is this the same Example Travel Tech mentioned on the About page, the same one whose founder wrote this article, the same one referenced in that press mention elsewhere on the web? Association is what answers that question definitively rather than leaving it to inference.
This is done through the @id property, which functions as a unique, stable identifier for a specific entity across every schema block on your site — and, where possible, across external references too. When your Organization schema uses @id: "https://example.com/#organization" on every page, and your Person schema's worksFor field references that exact same @id, and your Article schema's publisher field also references it, you're not describing three separate, loosely related things — you're explicitly telling every system reading your site that these are the same entity, connected in these specific, defined ways.
The practical effect of doing this consistently across a site: an AI system building its internal representation of "who is Example Travel Tech" encounters the same, consistently identified entity repeatedly, each encounter reinforcing rather than fragmenting that representation. A site where every page describes the organization slightly differently, with no explicit @id linking, forces the AI system to do the inference work of deciding whether these are the same entity — and inference, by definition, carries uncertainty that reduces citation confidence.
A simplified illustration of what a properly associated entity graph looks like across three connected schema blocks on a single site:
[
  {
    "@type": "Organization",
    "@id": "https://example.com/#organization",
    "name": "Example Travel Tech"
  },
  {
    "@type": "Person",
    "@id": "https://example.com/#founder",
    "name": "Jane Smith",
    "worksFor": { "@id": "https://example.com/#organization" }
  },
  {
    "@type": "BlogPosting",
    "headline": "How We Built Our Booking Engine",
    "author": { "@id": "https://example.com/#founder" },
    "publisher": { "@id": "https://example.com/#organization" }
  }
]
Three schema types, one connected graph — the article is written by the founder, who works for the organization, who published the article. Nothing here is left for a retrieval system to guess.
Service and Product Schema for Commercial Pages
For service-based businesses, Service schema (or Product schema for physical goods) marks up commercial offerings with the same explicit clarity applied to content elsewhere.
{
  "@context": "https://schema.org",
  "@type": "Service",
  "name": "Flight API Integration",
  "provider": {
    "@id": "https://example.com/#organization"
  },
  "areaServed": "Global",
  "description": "GDS, NDC, and aggregator API integration for online travel agencies and booking platforms."
}
Note the provider field again referencing the Organization @id rather than restating the organization's details independently — the same association principle applies here as everywhere else in this guide, and it's this consistency, not any single schema block, that builds a genuinely strong entity graph over time.
Validation: The Step Most Businesses Skip
Schema that's syntactically broken — a missing comma, a mismatched bracket, an incorrectly nested type — is either silently ignored or, worse, misread by the systems it's meant to help, which is functionally worse than having no schema at all in some cases, since it can send confusing or contradictory signals.
Google's Rich Results Test and the Schema Markup Validator (schema.org's own validation tool) should be run against every page carrying custom JSON-LD before publishing, and periodically afterward, since a site redesign or CMS update can silently break previously valid schema without anyone noticing until a rich result or citation rate unexpectedly drops. This is genuinely one of the highest-value, lowest-effort ongoing maintenance tasks in an AEO/GEO programme, and one of the most commonly neglected.
Common Mistakes in Schema Implementation
Marking up content that doesn't visibly exist on the page. Schema is a description of visible content, not a wishlist of what you'd like a system to believe is there — mismatches between schema and visible content are treated as manipulation, not optimization.
Treating schema types as interchangeable or applying them regardless of fit. Forcing HowTo schema onto content that isn't genuinely a linear process, or FAQPage schema onto content that isn't genuinely formatted as questions and answers, produces the same trust problem as the point above.
Building Organization and Person schema without any @id linking. This is the single most common missed opportunity covered in this entire guide — schema blocks that describe entities independently, without explicit association, leave exactly the ambiguity that a well-built entity graph is meant to remove.
Never validating, or validating once and never again. Schema breaks silently. A validation pass at launch that's never repeated leaves a site vulnerable to a slow, undetected loss of structured data signal over time as the underlying page templates change.
Duplicating or fragmenting schema unnecessarily. Multiple FAQPage blocks on one page, or Organization schema redeclared with slightly different details on every page instead of referenced consistently, works against the same entity-clarity goal this whole guide is built around.
"Most businesses treat schema as a technical checkbox — add FAQ schema, add Organization schema, done. The part that actually moves the needle for AI citation is the part almost nobody does: making every piece of schema on your site explicitly reference the same entity, consistently, everywhere. That's the difference between a site that mentions an organization and a site that unambiguously is one, as far as any system reading it is concerned. Association is the whole game."
— Jeffrey Mathew, Founder & CEO, Teckgeekz
Schema Markup for Travel Agencies and OTAs
Travel platforms carry a genuinely wider range of schema opportunities than most industries, because so much of the content — destinations, packages, hotels, reviews — maps naturally onto existing schema.org vocabulary built for exactly these purposes.
TouristTrip and TouristDestination schema can mark up destination guides and package pages explicitly, giving AI systems structured confirmation of what a page actually represents beyond generic Article schema — directly relevant to the destination content covered in our guide to multi-supplier hotel booking engine integration, where structured, consistent data about hotels, packages, and destinations is exactly the kind of content that benefits from explicit, machine-readable schema rather than free-form description.
Product schema for individual packages or room types, including pricing, availability, and review aggregate data where genuinely present, gives comparison-heavy travel queries — exactly the kind of query pattern covered in our guide to LLM citation optimization — the structured comparison data an AI system needs to synthesize a confident, specific answer rather than a vague generalization.
Organization schema with consistent @id referencing across every destination and package page matters disproportionately for travel businesses specifically, because travel platforms — including the kind of large-scale, programmatically generated destination content covered in our guide to building 50+ city pages that actually rank — often publish hundreds of pages. Without consistent entity association across all of them, a business risks its brand identity fragmenting across its own content rather than reinforcing itself, which is precisely the scale at which the association principle covered in this guide compounds most.
Frequently Asked Questions
What is JSON-LD and why is it used for schema markup?
JSON-LD (JSON for Linked Data) is a structured data format that embeds machine-readable information directly into a webpage's HTML, using the schema.org vocabulary that search engines and AI systems recognize consistently. It's the format Google and most AI platforms recommend, because it's added as a separate script block rather than woven into visible HTML, making it easier to implement and maintain without affecting page design.
Which schema types matter most for AEO specifically?
FAQPage schema is the most directly impactful for capturing featured snippets and People Also Ask visibility. HowTo schema supports process-driven content aimed at the same goal. Speakable schema, though less commonly implemented, directly targets voice assistant readout, which is a distinct AEO surface from visual snippets.
Which schema types matter most for GEO specifically?
Organization and Person schema, implemented with consistent @id linking across a site, matter most for GEO because they establish the entity clarity that AI citation confidence depends on. Article and BlogPosting schema with accurate authorship and date metadata also support GEO by reinforcing credibility and currency signals.
What does the @id property in schema actually do?
The @id property assigns a stable, unique identifier to a specific entity — an organization, a person, a specific piece of content — that can then be referenced by other schema blocks instead of being redescribed independently each time. This is what allows separate schema blocks across a site to explicitly declare they're referring to the same entity, building a connected entity graph rather than a set of isolated, ambiguous mentions.
Can incorrect or mismatched schema hurt my SEO or AI visibility?
Yes. Schema that misrepresents what's actually visible on a page, or that's applied to content it doesn't genuinely describe, is treated as a manipulation signal by search engines rather than a helpful addition, and can reduce rather than improve visibility. Schema should always accurately describe existing content, never wishful or inaccurate content.
How often should schema markup be validated or reviewed?
At minimum, whenever new schema is implemented and after any site redesign or CMS update, since template changes can silently break previously valid schema. A periodic review — quarterly is a reasonable cadence for most businesses — helps catch silent breakage before it causes a noticeable, hard-to-diagnose drop in rich results or citation visibility.
Key Takeaways
JSON-LD schema removes the ambiguity a machine otherwise has to resolve through inference — explicitly declaring what content is, not just what it says, which is foundational to both AEO extraction and GEO citation confidence.
FAQPage, HowTo, and Speakable schema are the priority AEO layer, each targeting a distinct extraction surface — snippets, process content, and voice readout respectively — and each should only be applied to content that genuinely matches that structure.
Organization and Person schema, connected through consistent @id referencing, are the priority GEO layer — and the association between schema blocks matters more than any individual block in isolation, since it's what converts isolated entity mentions into a single, unambiguous entity graph.
Validation is an ongoing maintenance discipline, not a one-time implementation step — schema breaks silently, and periodic review catches degradation before it causes a hard-to-diagnose visibility drop.
Travel platforms have unusually broad schema opportunities given how naturally destination, package, and hotel content maps onto existing schema.org vocabulary — and the scale at which travel businesses publish content makes consistent entity association particularly high-leverage.
How Teckgeekz Implements Schema for AEO & GEO
Every schema implementation we build treats association as a first-class concern, not an afterthought applied after the individual schema blocks are in place — because, as this guide has covered throughout, a site with technically valid but disconnected schema is leaving the majority of the GEO value on the table. This work sits within our full SEO, AEO & GEO services, connecting the technical implementation covered in this guide to the broader content structure and entity authority work covered across this series.
For travel businesses specifically, this connects directly into the platform architecture covered across our travel website development guides — a headless CMS with properly structured content, as covered in our guide to migrating travel websites from WordPress to Next.js, is exactly what makes consistent, scalable schema implementation possible across hundreds of destination and package pages, rather than a manual, inconsistent effort applied page by page.
In this Series — SEO, AEO & GEO:
SEO vs AEO vs GEO: What's the Difference and Why You Need All Three
How to Optimize Content for Google AI Overviews: A Practical Guide
How to Get Cited by ChatGPT, Perplexity, and Claude: A Guide to LLM Citation Optimization
Schema Markup for AEO & GEO: The Complete JSON-LD Implementation Guide
Digital PR for AI Search: How Brand Mentions Build LLM Trust and Citations (Coming soon)
Jeffrey Mathew
Founder & CEO • Travel Marketing Specialist
"With over 14 years of dominance in the travel and tech sectors, Jeffrey Mathew has engineered growth for hundreds of OTAs and airlines worldwide. He specializes in the intersection of Performance PPC and Agentic AI, building high-performance digital ecosystems for modern brands."
Start a Conversation
Ready to Elevate Your Business?
Fill out the form below and let's discuss how Teckgeekz can help you reach your goals.
Describe your project to unlock real-time AI service recommendations and matching portfolio cases.
Our Trusted Partners